E-crawl
High-Throughput Distributed Web Crawler
High-Throughput Distributed Web Crawler
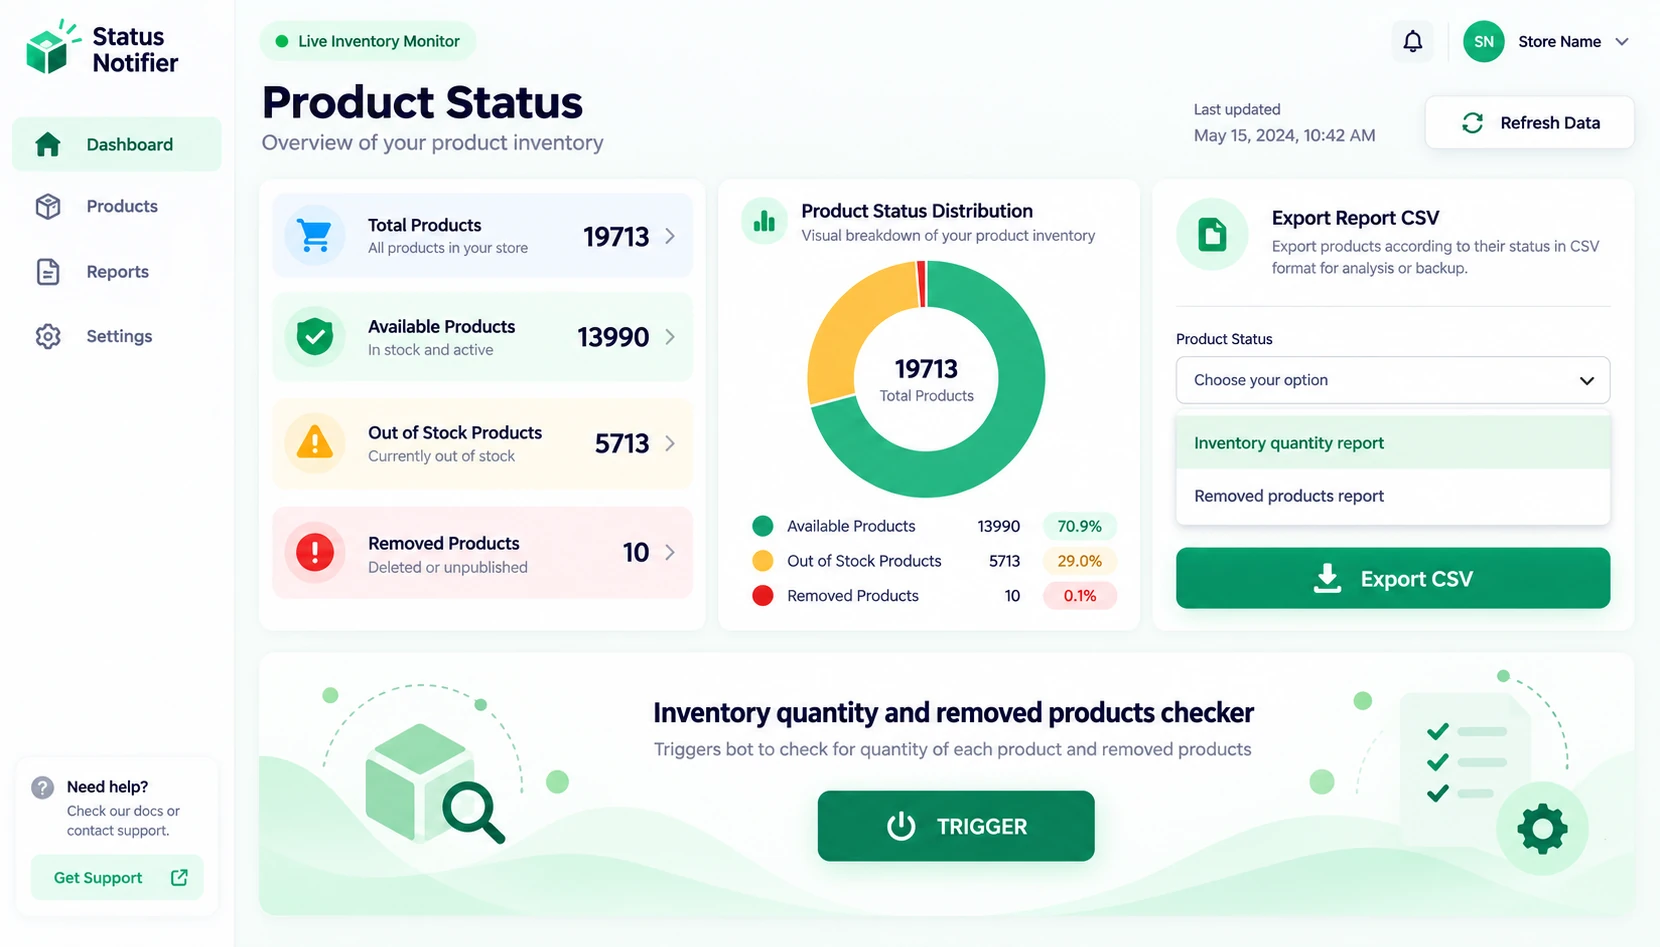
A high-volume drop-shipping eCommerce company managing an active catalog of over 40,000 product SKUs sourced from external manufacturer partner websites.
The client was experiencing severe order cancellation rates and unhappy customers because supplier websites frequently changed stock status without notifications. The existing scraping scripts took over 12 hours to run, failed mid-cycle, and caused expensive out-of-stock orders.
Role: Distributed Systems Architect & Backend Developer. Designed and implemented the crawler architecture, state management, retry logic, and monitoring.
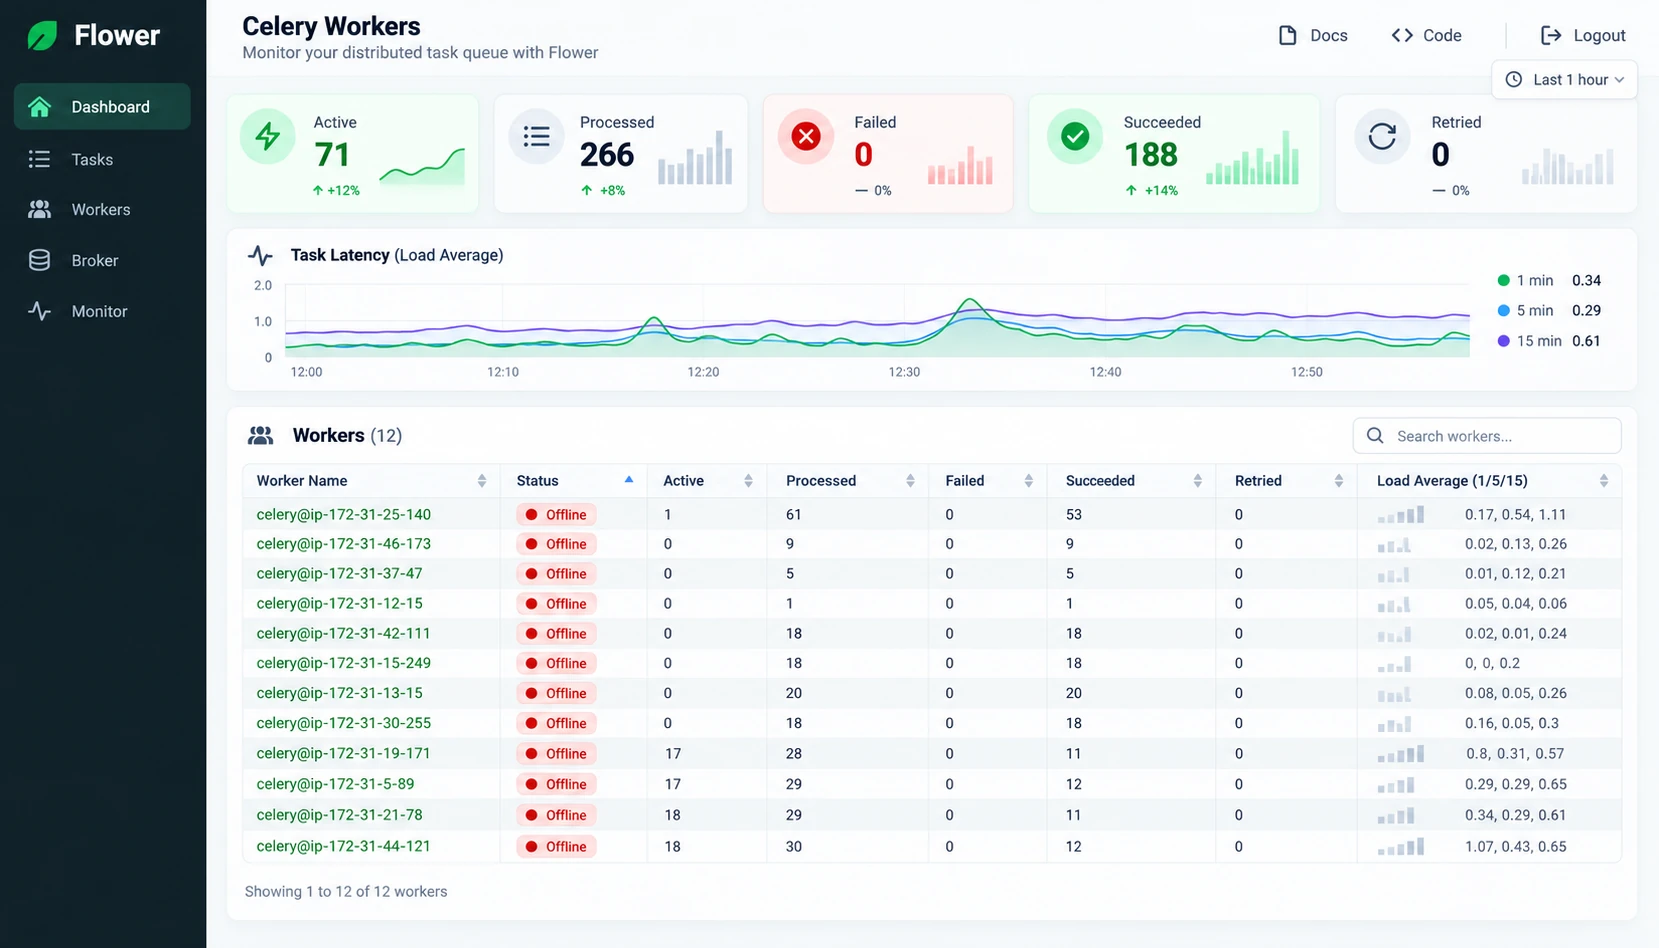
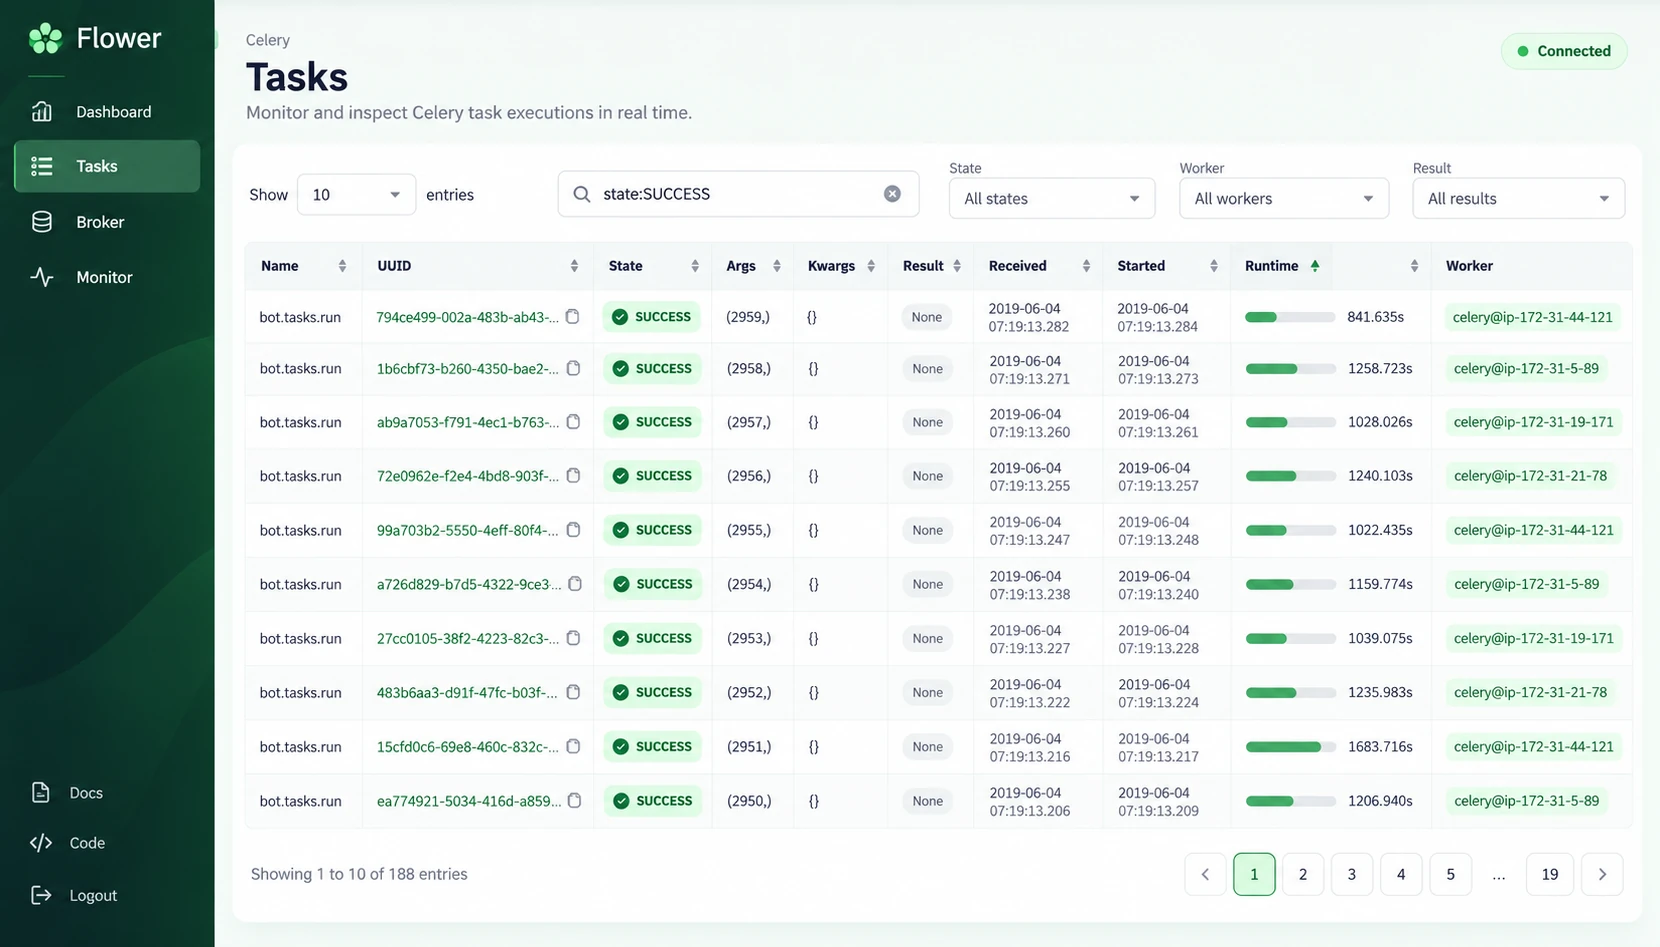
Engineered a distributed crawling cluster utilizing Python, Celery task distribution, and PostgreSQL for state synchronization. Designed an intelligent scheduler with exponential backoff, checkpoint resumption from points of failure, and adaptive rate-limiting to avoid IP bans.
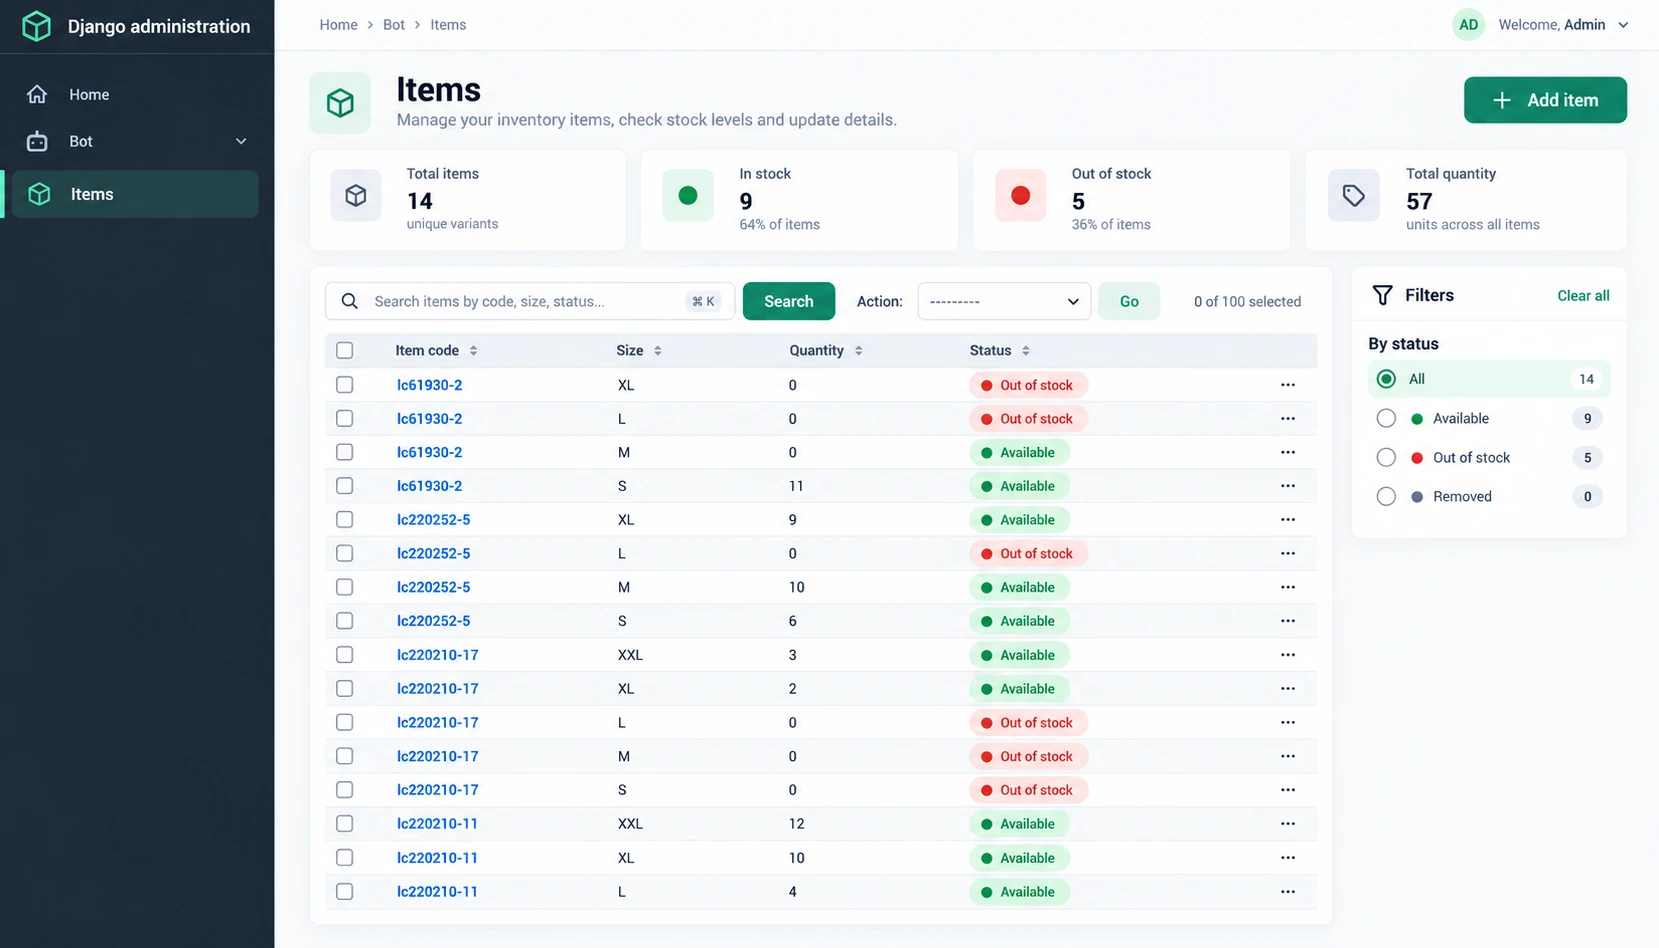
Click any screenshot to expand.